Best DevOps Companies in 2026 What Real DevOps Capability Looks Like
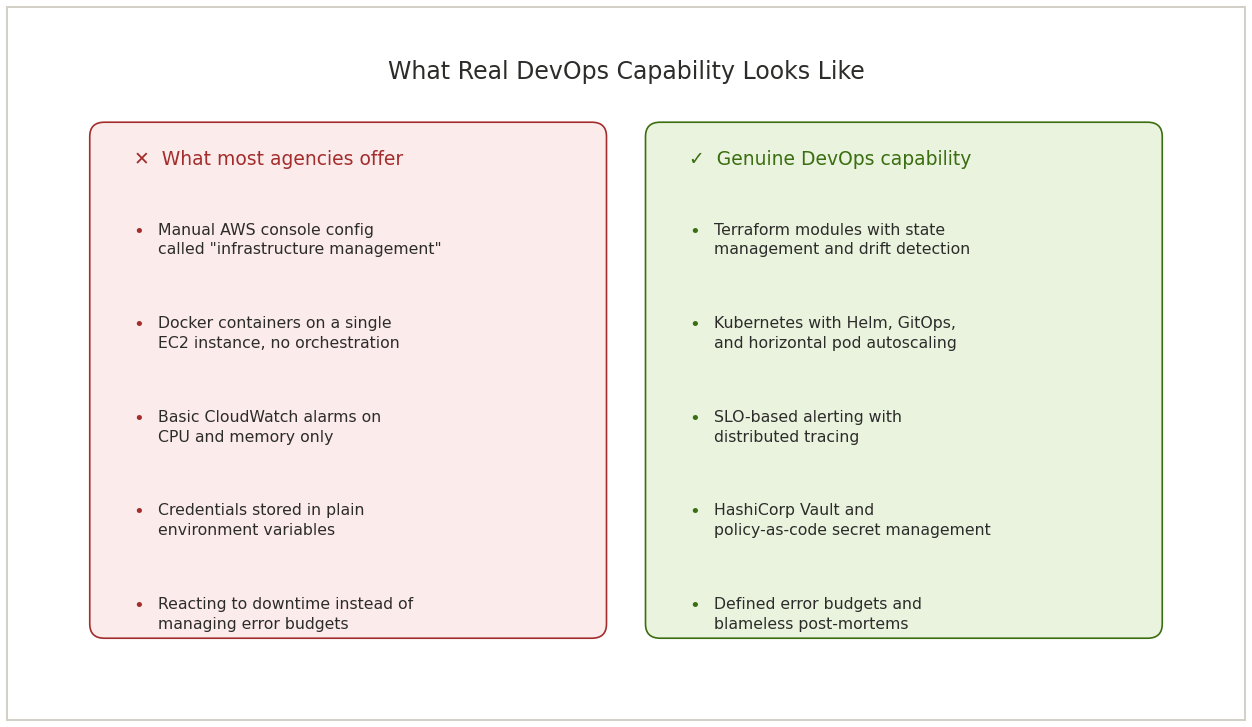
DevOps is the most over-labelled discipline in technology services. A decade ago, every server administrator became a “systems engineer.” Five years ago, every systems engineer became a “DevOps engineer.” Today, agencies that configure AWS EC2 instances and write basic bash scripts describe themselves as DevOps companies. The actual DevOps discipline culture, automation, measurement, and sharing (CAMS) applied to the software delivery pipeline requires engineering sophistication that most “DevOps companies” do not possess.
That’s why choosing the best DevOps companies requires evaluating real experience with CI/CD, cloud infrastructure, Infrastructure as Code, monitoring, security, and automation, not simply checking whether an agency offers DevOps services.
According to Grand View Research – Development to Operations Market Report, the global DevOps market is estimated at $18.1 billion in 2026 and is projected to reach $37.2 billion by 2030, growing at a 16.8% CAGR.
The global DevOps market is valued at $25.5 billion in 2026, growing at 19% annually. The buyers are engineering teams that need to: ship faster and more reliably, reduce manual deployment overhead, build observability into their systems, manage cloud costs that have quietly outgrown the original budget, or achieve security and compliance certifications that require infrastructure controls. This guide covers how to find an agency genuinely capable of delivering these outcomes.
What Real DevOps Capability Covers
The DevOps discipline broken into its actual components:
| Component | What It Involves | What Most “DevOps” Agencies Actually Offer |
| CI/CD pipelines | Automated build, test, and deployment pipelines that run on every commit | Basic GitHub Actions or CircleCI setup often just configuration, not engineering |
| Infrastructure as Code | Defining infrastructure in version-controlled code (Terraform, Pulumi) so environments are reproducible | Manual AWS console configuration called “infrastructure management” |
| Container orchestration | Running applications in containers (Docker) managed by an orchestration platform (Kubernetes, ECS) | Running Docker containers on single EC2 instances without orchestration |
| Observability | Comprehensive logging, metrics, tracing, and alerting so engineers know when things break and why | Basic CloudWatch alarms on CPU and memory |
| Security (DevSecOps) | Integrating security scanning, secret management, and compliance controls into the pipeline | Security as an afterthought, credentials in environment variables |
| Cloud cost optimisation | Architecting infrastructure for cost efficiency, rightsizing, reserved instances, spot instances | Deploying whatever the application needs without cost review |
| SRE practices | Defining SLOs, error budgets, incident response, and blameless post-mortems | Reacting to downtime rather than proactively managing reliability |
DevOps Services at the $5K–$30K Budget Level
The $5K to $30K range covers meaningful DevOps work not a full-scale enterprise DevOps transformation, but specific, high-impact improvements to a startup or SME’s engineering infrastructure. Budgeting for this accurately depends on the same variables that shape how software project costs typically break down by scope: complexity, region, and how well-defined the existing infrastructure already is.
The most common DevOps engagements at this budget:
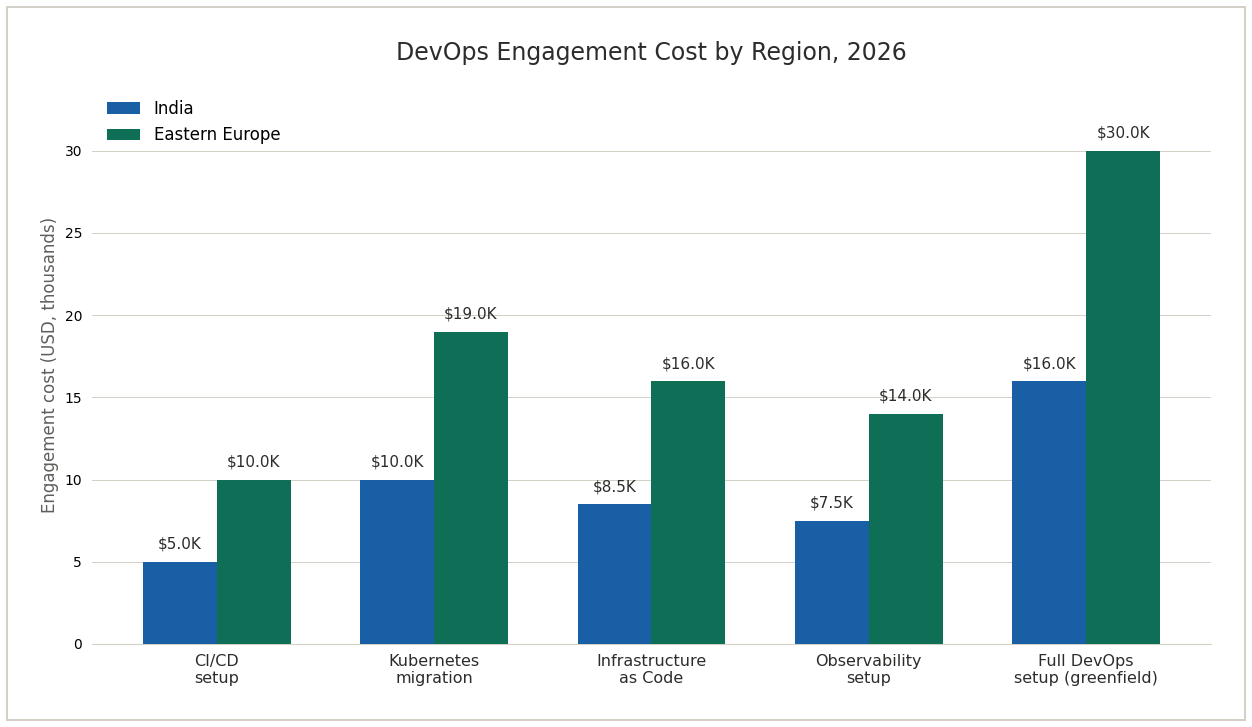
| Service Type | What It Delivers | India Cost | Eastern Europe Cost | Timeline |
| CI/CD pipeline setup | Automated testing + deployment pipeline for existing codebase (GitHub Actions / GitLab CI) | $3K–$7K | $6K–$14K | 3–6 weeks |
| Kubernetes migration | Moving from EC2/VM deployment to containerised Kubernetes deployment | $6K–$14K | $12K–$26K | 6–12 weeks |
| Infrastructure as Code (IaC) | Terraform or Pulumi describing all existing infrastructure + automation | $5K–$12K | $10K–$22K | 5–10 weeks |
| Observability setup | Centralised logging + metrics + distributed tracing + alerting (Datadog, Grafana stack, OpenTelemetry) | $5K–$10K | $10K–$18K | 5–9 weeks |
| Cloud cost audit + optimisation | Analysis of current AWS/GCP bill + rightsizing + reserved instances + architecture improvements | $4K–$8K | $8K–$15K | 3–6 weeks |
| DevSecOps implementation | Secret management (Vault), container scanning, SAST in pipeline, compliance controls | $6K–$12K | $12K–$22K | 6–10 weeks |
| Full DevOps setup (greenfield) | CI/CD + IaC + containerisation + observability for new product | $10K–$22K | $20K–$40K | 10–18 weeks |
| SRE setup + runbook development | SLO definition, error budgets, incident response procedures, on-call setup | $5K–$12K | $10K–$22K | 5–10 weeks |
The Technologies That Genuinely Capable DevOps Teams Know
When evaluating a DevOps agency, the specific technologies they are proficient in are more revealing than their generic claims about DevOps expertise.
The 2026 DevOps technology stack:
| Category | Standard Tools | What Agencies With Genuine Expertise Know |
| CI/CD | GitHub Actions, GitLab CI, Jenkins, CircleCI | Pipeline optimisation, parallel execution, test splitting, deployment strategies (blue-green, canary) |
| Containers | Docker, containerd | Multi-stage builds, image optimisation, security scanning (Trivy, Snyk) |
| Orchestration | Kubernetes (EKS, GKE, AKS), AWS ECS | Helm, Kustomize, GitOps (ArgoCD, Flux), horizontal pod autoscaling, resource limits |
| IaC | Terraform, Pulumi, AWS CDK | Module design, state management, drift detection, workspace organisation |
| Observability | Datadog, Prometheus, Grafana, OpenTelemetry, ELK stack | Trace correlation, SLO alerting, cardinality management, cost-effective log aggregation |
| Security | HashiCorp Vault, AWS Secrets Manager, Trivy, Checkov, OPA | Policy as code, SBOM generation, CVE remediation workflows |
| Cloud platforms | AWS, GCP, Azure | Multi-account architecture, landing zones, cost allocation, FinOps |
| GitOps | ArgoCD, Flux, Weaveworks | Declarative deployments, rollback strategies, multi-cluster management |
The technology stack question that reveals expertise:
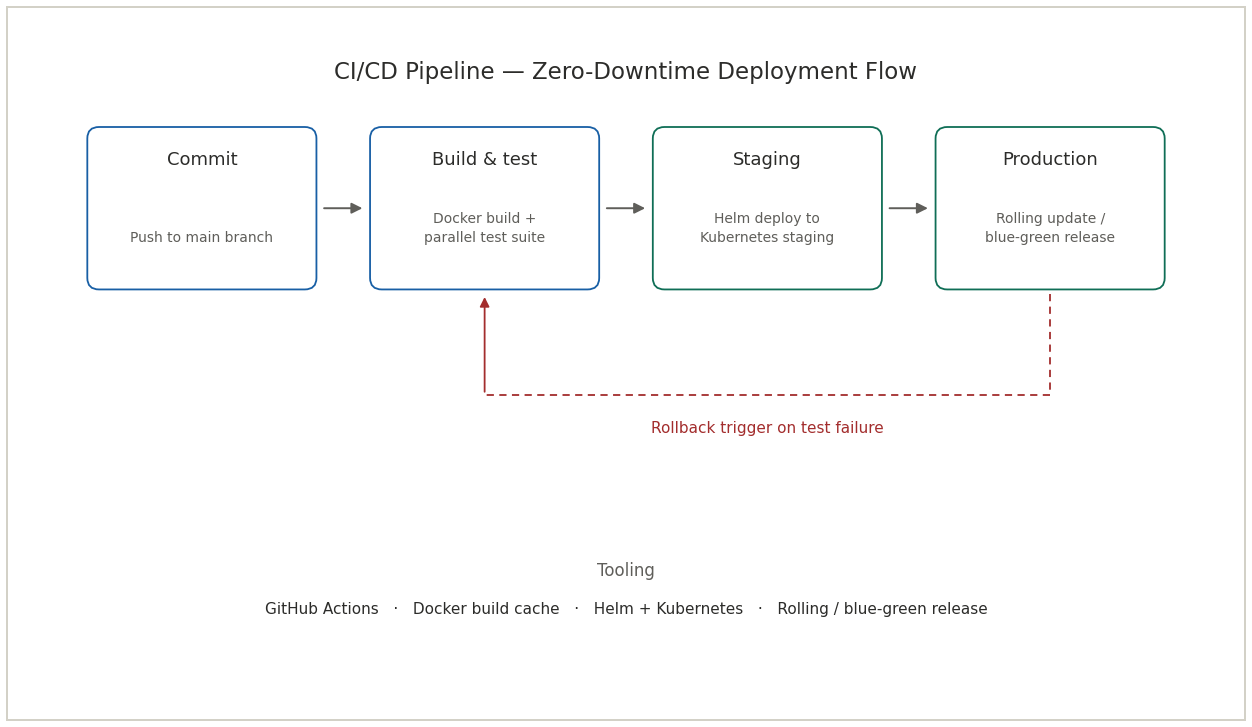
Ask the agency to describe how they would set up a CI/CD pipeline for a containerised Node.js application with automated tests, staging deployment, and production deployment with zero-downtime rolling updates. A complete answer describes: GitHub Actions workflow structure, Docker build caching strategy, test parallelisation, staging environment deployment via Helm to Kubernetes, production deployment strategy (rolling update or blue-green), and rollback trigger on test failure. A partial answer describes “we set up GitHub Actions and deploy to AWS” without architectural specifics; it’s worth holding vendor answers here to the level of specificity you should expect from any software development contract, since vague scope in either place tends to predict the same outcome.
The Observability Gap Why Most DevOps Setups Fail Quietly
The most common DevOps failure mode is an engineering team that has automated deployments but has no idea what is happening in production. This gap usually traces back to a statement of work that never defined monitoring as a deliverable in the first place if it isn’t scoped, it doesn’t get built. Observability: the ability to understand a system’s behaviour from its outputs is the component of DevOps that is most consistently underinvested and most valuable when things go wrong.
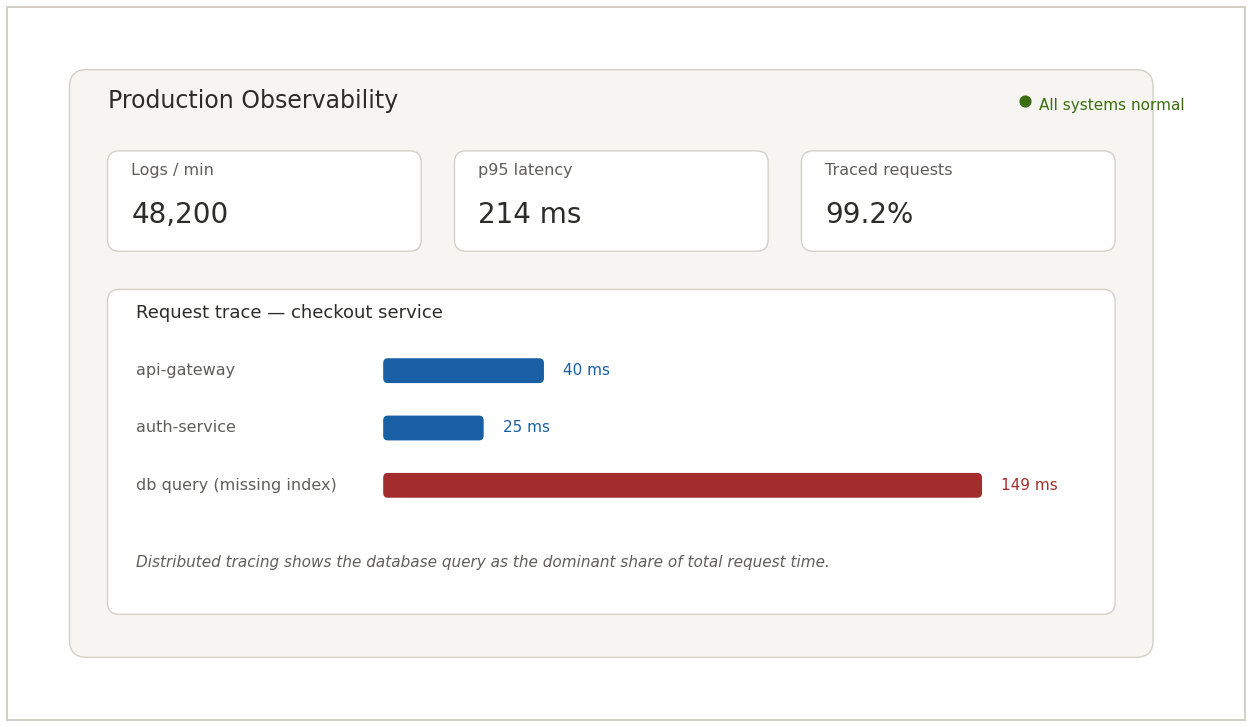
The three pillars of observability and what they provide:
Logs tell you what happened. When something breaks, logs show the sequence of events: what was called, what returned an error, what state the system was in at the time. Without centralised, structured logging, debugging production issues means SSH-ing into servers and reading log files manually which is how engineering teams spend 6 hours on an incident that should take 20 minutes.
Metrics tell you how things are performing. CPU, memory, request latency, error rate, queue depth the quantitative signals that tell you whether your system is healthy before users start complaining. Metrics without alerting are dashboards nobody watches. Metrics with SLO-based alerting are the early warning system that catches degradation before it becomes an outage.
Traces tell you where time is spent in a distributed request. A user request that takes 4 seconds might be spending 3 of those seconds waiting for a database query that is missing an index. Distributed tracing surfaces this showing the full request lifecycle from the user’s browser through every microservice, queue, and database it touches.
The observability setup cost:
A complete observability setup for a typical startup application centralised logging with structured search, metrics with SLO alerting, and distributed tracing costs $5,000 to $10,000 to implement correctly with a strong Indian DevOps agency, plus $100 to $500 per month in tooling costs. Structuring that spend against clear checkpoints is where how milestone-based payment structures keep this kind of spend accountable becomes useful observability work that is easy to scope loosely and hard to verify without defined checkpoints.
How to Evaluate a DevOps Agency
The portfolio signals that matter:
Case studies with specific outcomes “reduced deployment frequency from weekly to 20 times per day” and “reduced mean time to recovery from 4 hours to 12 minutes” are specific, verifiable claims. Generic claims about “improved DevOps practices” are not evaluable. This is the same evaluation criteria that apply when choosing an AI development company specificity in outcomes, not category labels, is what actually separates vendors.
As Code repositories some DevOps agencies make their open-source Terraform modules or GitHub Action templates public. The quality of these artefacts is a direct signal of their IaC engineering quality.
Certifications AWS Certified DevOps Engineer, Google Professional DevOps Engineer, Certified Kubernetes Administrator (CKA) are not sufficient on their own but indicate baseline exposure to the relevant platforms and practices.
The conversation test:
Ask them to describe a production incident they helped resolve and what observability infrastructure made the resolution possible. A genuine DevOps team describes the specific signals that surfaced the issue: a latency spike on a specific trace, an error rate alarm, a log pattern that indicated the root cause and the resolution process. A team with shallow experience describes generic troubleshooting steps without specific tooling references. It’s also worth checking how hourly rates vary by country for this kind of specialised engineering talent before comparing quotes, since a lower rate on paper doesn’t always reflect equivalent DevOps depth.
Frequently Asked Questions
What is the difference between DevOps and SRE?
DevOps (Development and Operations) is a cultural and organisational approach that breaks down the traditional barrier between development teams who write code and operations teams who run it combining their practices so that software is built, deployed, and operated as a shared responsibility. SRE (Site Reliability Engineering), a practice originated at Google, applies software engineering principles to operations problems defining reliability targets as Service Level Objectives, quantifying acceptable unreliability as an error budget, and using that budget to make decisions about feature velocity vs reliability work. In practice, many organisations use the terms interchangeably. The meaningful distinction: DevOps focuses on the cultural change and the delivery pipeline automation; SRE focuses on measuring and managing reliability of running systems. Both are relevant for most engineering teams above a few engineers.
When does a startup need to invest in DevOps infrastructure?
The practical threshold: when manual deployments take more than 30 minutes per week, when production incidents regularly take more than an hour to diagnose, or when the team is above 5 engineers. Before these thresholds, DevOps overhead typically exceeds the value. After them, DevOps investment has clear ROI. Specific triggers that justify immediate DevOps investment: a security or compliance requirement (SOC 2, ISO 27001, HIPAA) that requires documented pipeline controls; a reliability incident caused by a manual deployment error; an engineering team that is spending more than 20% of their time on deployment and infrastructure management; or a need to scale deployment frequency from weekly to daily to support faster product iteration.
What is Infrastructure as Code and why is it important for growing engineering teams?
Infrastructure as Code (IaC) means defining your cloud infrastructure servers, databases, load balancers, security groups, networking in version-controlled code files rather than through manual console configuration. The importance for growing teams: reproducibility (you can spin up an identical staging environment from the same Terraform code that manages production no “works on staging, breaks in production” discrepancies caused by environment drift), auditability (every infrastructure change is a pull request with a review and a commit history you always know who changed what and when), and disaster recovery (if your production environment is destroyed, you can recreate it from code in minutes rather than days of manual reconstruction). The investment required: a DevOps engineer typically needs 5 to 12 weeks to write IaC for an existing production environment that was set up manually, depending on complexity.